What Natural Language Site Search Needs From Your Product Data
Site search on eCommerce sites is changing. For most of the last two decades, the search box matched the words a shopper typed against the words in a product record. The newer generation of site search and discovery platforms is built to do something closer to understanding. A shopper can type “a modest dress for an October evening wedding” or “a rain jacket that packs small for travel,” and the platform tries to work out what they mean, not only which words they used. Several of these platforms are also adding conversational interfaces, where a shopper refines a request over a few exchanges, much as they might with a store associate.
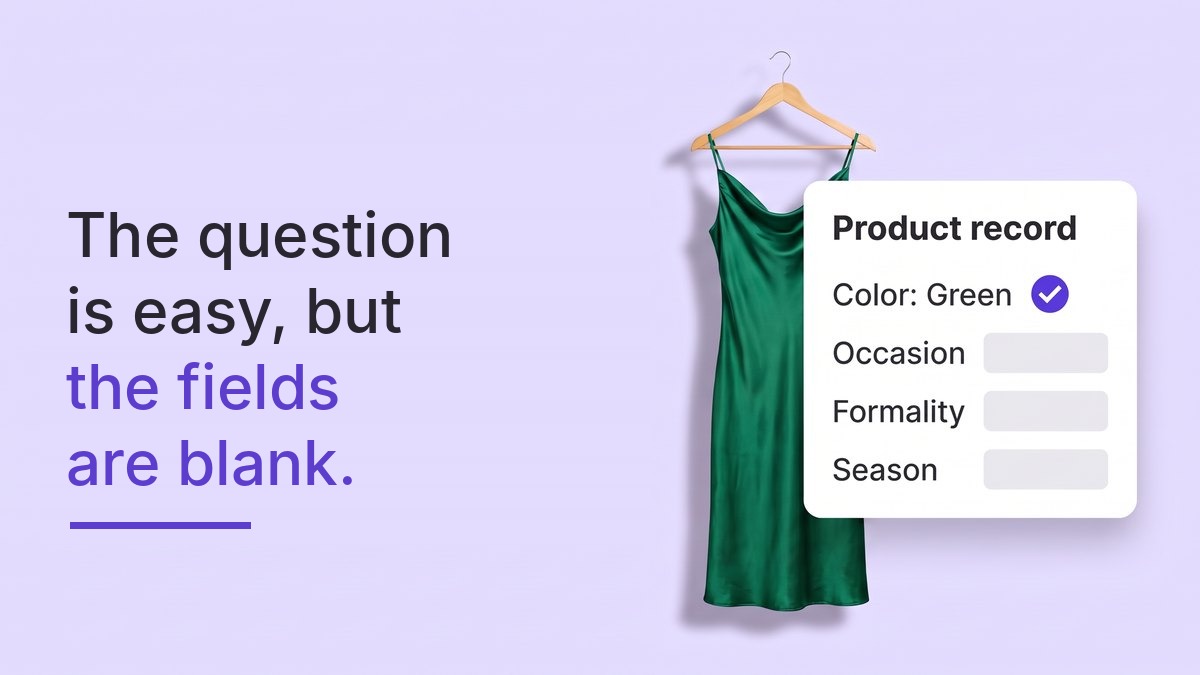
The demonstrations are persuasive, but what the demonstrations tend to leave out is the condition of the product data that the results depend on. A platform can interpret a shopper’s request very well and still have little in the product data to match it against. During one of our customer conversations this fall, we watched a site’s built-in search handle the query “dress for casual dinner night.” It returned no results at all.
This post looks at that gap, between what the platform can understand and what the product data can answer. In many catalogs, the data side turns out to be the harder of the two problems to solve.
The platform interprets the question. The product record has to answer it.
Natural language search usually works in two steps. First, the platform interprets the query. It identifies the product type, the qualities the shopper cares about, and the context around the request. Second, it looks for products whose records match that interpretation.
Language models have made the first step much better. The second step still depends on what each product record contains. If a shopper asks for a dress for an evening wedding, the platform needs some way to know which dresses are formal enough, which suit an evening event, and which offer the coverage the word “modest” implies. When those qualities are recorded as attributes, the match is direct. When they appear only in a photograph or loosely in a marketing description, the platform has to infer them, and the result depends on how well that inference works for each product. When they are recorded nowhere, the product cannot be found by that request, however well the request was understood.
Some platforms now generate attributes of their own from descriptions and images, and that can help. It also has limits worth knowing about. The platform can only infer what is present in the text and images it receives. The attributes it produces are not always reviewed by the business. And they usually live inside that one search tool, where the marketplace feed, the comparison page and the AI agent that need the same answers cannot use them.
This is one reason two retailers using the same search platform can see quite different results. The platform is the same. The data underneath it is not.
We have been here before
Anyone who worked in eCommerce in the 2000s may recognize the pattern. When faceted, or guided, navigation arrived, with platforms such as Endeca, it promised that shoppers could narrow a large assortment by the qualities they cared about: size, color, material, fit, price. The technology worked. What many retailers found during implementation was that their product data could not support it. Attributes were missing, inconsistent, or stored as free text. Filters launched with a handful of values, and a long tail of products appeared under none of them. For many organizations, the navigation project became an attribute project, and the attribute work took far longer than the software.
Natural language search brings a similar inflection point, with one important difference. A filter works from a defined list of attributes and values. Someone decides in advance that dresses will have a neckline filter and that it will offer five options. A natural language query has no such boundary. A shopper can ask about occasion, season, how a fabric feels, what a product pairs with, or whether a part fits a unit they already own. The set of attributes that could be useful is larger, harder to predict, and more dependent on context than anything a faceted design required.
What “enough data” looks like
It can help to think about the data natural language search needs in layers.
The first layer is the core attributes most catalogs already try to maintain: product type, size, color, material, dimensions, and brand. These are necessary, but on their own they rarely answer a conversational query.
The second layer is descriptive attributes that capture how a product is used and judged: occasion, formality, silhouette, season, fit, care, and intended use. These are the attributes that let a platform match “something for an evening wedding” to the right products. They are also the attributes merchandising teams most often plan to add and seldom have time to. We have written separately about why a tag and an attribute are not the same asset, which matters here, because a search platform can compare attributes in a way it cannot compare loose tags.
The third layer is shopper language. Shoppers and brands often describe the same product differently. A brand might call a product a facial soap while its customers consistently call it a cleanser. Search platforms handle some of this with synonym lists, but a record that already reflects how customers describe a product gives the platform more to work with.
A fourth element runs across all three layers: the relationships between products. Sets and coordinates, items that complete an outfit, compatible parts and accessories, and the newer versions of discontinued items all help a platform answer requests that are really about more than one product.
The same reasoning applies to industrial and distribution catalogs, with different vocabulary. A buyer who searches for “half-inch brass ball valve rated for 600 psi” is asking a natural language question made almost entirely of specifications. The platform can parse it. Whether it returns the right valve depends on whether pressure ratings, connection sizes, and materials are recorded as structured values in one consistent unit convention, or are scattered across titles and spec sheets in several.
The second problem: the data exists, but not where search can use it
If the missing attributes simply did not exist, the answer would be to create them. In practice, much of the information already exists somewhere in the business. It is just not in the product record that feeds search.
A product’s construction details may sit in a product lifecycle management system or a tech pack. Its neckline, pattern, and silhouette are visible in its photography, but no field records them. How it fits, and the words customers use for it, appear in reviews. In industrial categories, specifications often sit in manufacturer documents that were never fully entered. Several of the eCommerce leaders we spoke with this fall described teams re-keying attributes from one system into another for every new collection.
That is what makes sourcing difficult. The information is spread across systems with different owners, formats, and update cycles, and much of it is unstructured. Many of the AI features now available in commerce tools work from the data already loaded into them. They can rewrite a description or fill a field from text that is already present, which is useful. They are not designed to look at a photograph, a tech pack, or a set of reviews and bring back an attribute that never entered the system.
Getting the data in is half the work. Getting it right is the other half.
Sourcing attributes from unstructured material raises a fair question, and it came up repeatedly in our conversations: who checks the output?
The question matters more for search than for most other uses of product data, because a search platform takes attributes at face value. If an attribute is missing, the product is not found for that request. If an attribute is wrong, the product is found for the wrong request and shown to a shopper it does not suit. The first costs a sale. The second costs a sale and some of the shopper’s confidence in the search box.
So the attributes that feed search need to be checked before they get there. Values should come from a controlled vocabulary for the category rather than from free text. Units should be consistent, so that every pressure rating or fabric weight in a category can be compared with every other. Each generated value should carry a record of where it came from and how confident the system is in it, so that people review the exceptions rather than every record. At atronous we keep these jobs deliberately separate: AI generates attribute values, and deterministic, category-specific rules validate them before they are delivered.
Where atronous fits
Atronous builds the product record that these platforms read. It brings in information from the sources described above, including product systems, tech packs, images, and customer reviews, and generates the attributes a category needs, including attributes a team has not yet defined in its own schema. Each value is validated against the rules of its category before delivery. The result goes to the systems a business already runs, such as its PIM and commerce platform, and from there to site search, marketplaces, and the feeds AI agents read.
Search is one application of this work. For retailers with large assortments, it is often the one with the clearest connection to revenue, because shoppers who search are usually close to a purchase. It is not the only application. The same validated record supports marketplace listings, product comparison, and the AI agents that are beginning to recommend products on a shopper’s behalf. We have written about how AI agents decide on attributes and about what product data enrichment actually requires. Building the foundation once, rather than enriching data separately for each channel and each tool, is what lets the investment carry across all of them.
Where this matters most, and where it matters less
It is worth being specific about where this applies. In our conversations, the retailers most concerned about search had large assortments. Their shoppers engage more in product discovery and tend to describe what they need rather than name a product: a dress for an occasion, shoes for an activity, jewelry for a style or a gift. Smaller, brand-led catalogs are often searched by product name, and one leader we spoke with placed site search well down a list of priorities for exactly that reason. For businesses like that, the same data work tends to pay off more through organic search and visibility in AI assistants than through the site search box.
Industrial and distribution catalogs sit somewhere in between. Many buyers search by part number, which keyword search already handles well. The opportunity there is in searches that describe a requirement rather than a part, and that is where normalized specifications decide what is found.
Questions to ask before evaluating a natural language search platform
A few questions can show how ready a catalog is before an evaluation begins.
Which searches return nothing today, or return the wrong products? Most search platforms report zero-result and low-engagement queries. Reading the top fifty and asking, for each one, which attribute would have answered it is a useful exercise.
In your three largest categories, which descriptive attributes are filled in, and for what share of products? Coverage of core attributes is often high. Coverage of occasion, use, fit, and compatibility is usually much lower, and those are the attributes conversational queries depend on.
Where does the missing information live today? If it is in photography, product systems, documents, or reviews, it can be sourced. If it exists nowhere, it has to be created, and the plan should say who will create it.
Who checks the attributes before they reach search, and how? Reviewing every record by hand will not hold at the scale natural language search asks for. Review early output closely to confirm it is right, then rely on validation rules that check every record automatically and send only the exceptions to a person.
How will you measure the result? The leaders we spoke with tend to fund this kind of work after a measured test: a defined slice of the catalog, a comparison against a control, and a result expressed in search revenue per visitor or search conversion. Planning the measurement before the work begins makes the result easier to act on.
Looking ahead
Natural language search and conversational commerce are developing quickly, and the platforms will keep getting better at understanding what shoppers mean. That progress is likely to make the condition of product data more visible, not less. A platform that understands a request precisely will also make it clear when the catalog cannot answer it.
See how your own data would hold up
The atronous Data Quality Assessment takes up to 50 SKUs from your PIM or ERP, exactly as they are today, and runs them through the same pipeline our enterprise customers use. Within five business days you receive the sample back, generated and validated, with the taxonomy and schema recommendations behind the work and a working session to walk through what we found.
Request your Data Quality Assessment, or see how atronous works with apparel brands.
Intelligence in every attribute.
Frequently asked questions
What is natural language search in eCommerce?
It is site search that interprets what a shopper means rather than matching only the words they typed. A shopper can describe a need, such as a dress for an evening wedding or a valve rated for a given pressure, and the platform works out the product type and qualities involved. Conversational search extends this by letting the shopper refine the request over several exchanges.
Why does natural language search need more product data than keyword search?
Because shoppers can ask about anything: occasion, season, fit, compatibility, how a product is used. A keyword search or a filter works from a fixed set of terms and values. A natural language query can only be matched to products whose records describe the qualities it asks about, so the useful set of attributes is larger and harder to predict.
Can a search platform infer missing product attributes on its own?
To a degree. Some platforms generate attributes from descriptions and images, which helps. They can only infer what is present in the content they receive, the results are not always reviewed, and the attributes usually stay inside that one tool. Attributes recorded and validated in the product record itself are consistent and can be reused by every channel that reads it.
Which product attributes matter most for natural language search?
Beyond core attributes such as size, color, and material, the attributes that answer conversational queries are descriptive ones: occasion, formality, season, fit, care, intended use, and, in industrial catalogs, normalized specifications. Relationships between products and the language customers use to describe them also improve how well a platform matches a request.